
What Structured Data Actually Does — And Why the Translation Has to Be Exact
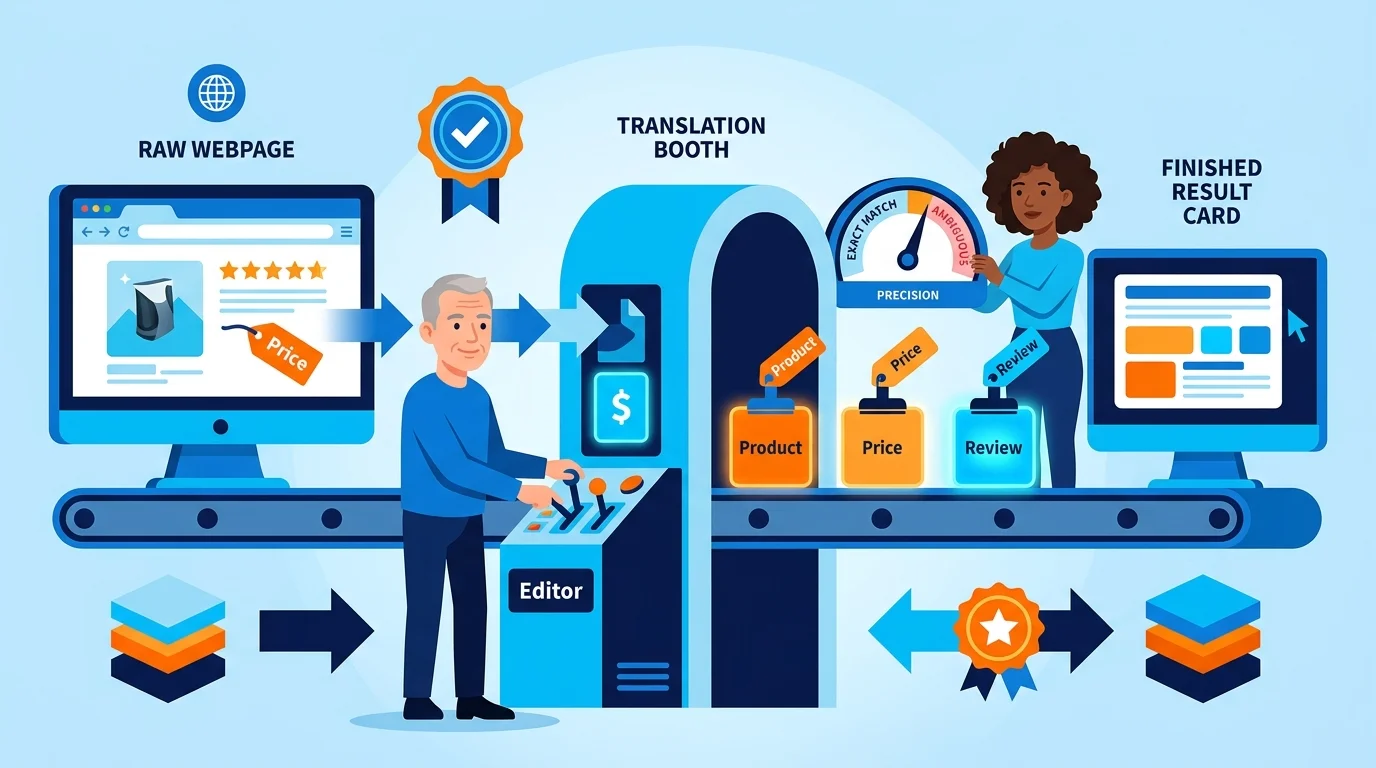
Here's the thing: schema markup is a translation layer. It sits between what a site shows people and the machine trying to read it.
That translation can be fluent, or it can be broken. A broken translation leaves the underlying content invisible to the system trying to interpret it, no matter how well it was written for a human.
The Vocabulary Search Engines Actually Read
Schema markup (structured data, same thing) is a vocabulary that turns a site's content into a language search engines can read without guessing. It swaps guesswork for explicit labels. A number on the page stops being a mystery and declares what it means, whether that's a price or a review score.
According to Roderic Page (University of Glasgow, 2019), one motivation for the development of schema.org may be to encourage the inclusion of structured data in web pages, which can help search engines interpret their contents. Now… that purpose hasn't budged as search evolved. The translation still has to kill ambiguity, and piling on tags won't do that job.
Why Ambiguity Is the Enemy of Machine Interpretation
Ambiguity is the one thing machine readers can't handle. A human sees a name on a page and figures it's the author. A crawler needs that relationship spelled out.
Without the explicit label, the system either guesses wrong or ignores the content entirely. Guessing wrong is how a practice ends up miscategorized in results it should own. Ignoring the content is worse: it means the page effectively does not exist for that system. For readers weighing whether can a clinic earn AI citations without rebuilding its site is realistic, the answer starts with this translation layer, not with a full redesign.
Where a Shaky Translation Comes From
Here's what I know: a shaky translation rarely comes from laziness. It comes from treating markup like a box someone checks once and then forgets about.
Why Treating Markup as a One-Time Checkbox Fails
Cheap retainers built around a one-time schema setup treat structured data as a static asset rather than a living description of the page. A site's content changes, new services get added, and the markup describing it stays frozen at whatever it was the day it was installed. The gap between what the page says and what the code declares widens with every update nobody reflects back into the markup.
That gap is where a machine reader starts trusting the page less. A mismatch between visible content and declared structured data does not just sit idle; it actively mislabels the page to any system parsing it. For teams adding schema markup for new clinic articles, the same discipline applies: markup needs to track the content, not just launch alongside it.
The Guideline Gaps That Produce Bad Annotations
Most of this drift traces back to gaps in how annotation guidance actually gets applied. The paper by Panasiuk et al. (University of Innsbruck, 2019) notes in its introduction that schema.org annotations may be commonly incorrect due to missing guidelines, insufficient expertise, and technical or human errors, which can make content unreachable for automated agents. Missing guidance, thin expertise and plain old technical slip-ups are different problems, but they all land in the same place: content a crawler can't reliably reach.
What Broken Markup Costs When the Reader Is a Machine
A machine reader does not grade markup on effort. It either resolves cleanly or it does not.
When it fails silently, nothing crashes and no error surfaces to a human visitor. The page simply stops being eligible for the systems that depend on clean structure.
| Eligibility Factor | What It Requires | What Breaks It |
|---|---|---|
| Technical requirements beyond indexing | No additional technical requirements past standard Search eligibility | Treating markup as a separate hurdle instead of meeting the same baseline every indexed page already meets |
| Precision of technical signals | Markup that accurately reflects the page as search engines evolve into answer engines | Drifted or mislabeled structured data that degrades the signal AI-generated results depend on |
How Flawed Schema Fails Silently Inside an AI Pipeline
According to Google's documentation, a page may be eligible to appear as a supporting link in AI Overviews or AI Mode if it is indexed and eligible to be shown in Google Search with a snippet, with no additional technical requirements.
That bar does not reward elaborate markup. It only asks whether the page qualifies at all, which is a narrower test than most teams assume.
For teams tracking post-publication expectations for a standalone content pack, meeting that bar is what keeps a page eligible after launch, not just on launch day.
Plugin Automation vs Custom Markup — Where the Line Actually Sits
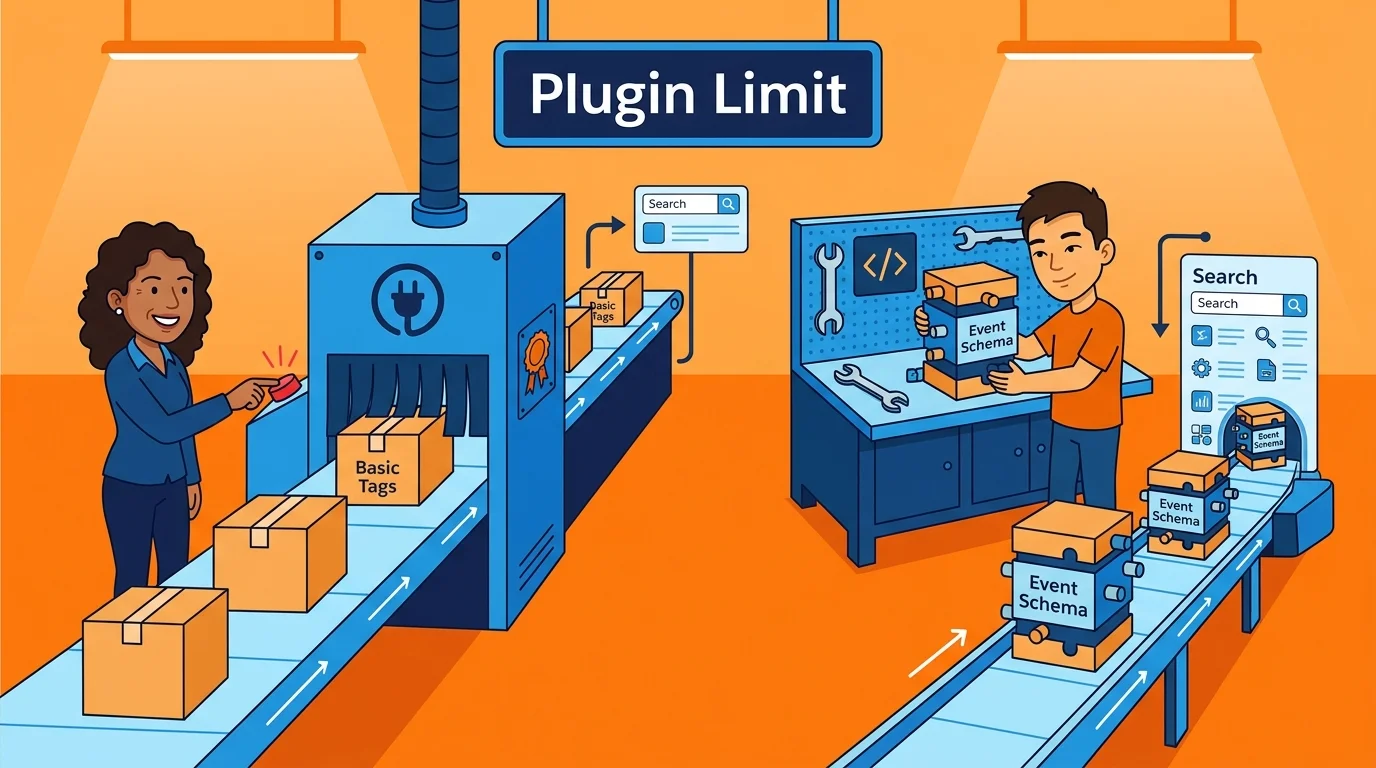
More structured data is not the same as better structured data. A market that treats schema as a volume game misreads what actually earns a citation. The system rewards accurate description, not the quantity of tags stacked onto a page.
| Markup Task | Plugin Approach | Developer Approach |
|---|---|---|
| Business name, address, and basic contact markup | Handles this reliably with minimal setup | Overkill for a task this standardized |
| Standard blog or article schema | Templated fields map well to this content type | Adds precision only if custom fields are needed |
| Single product or service listing | Fills in matching fields automatically | Unnecessary unless pricing or variants get complex |
| Nested or multi-entity relationships on one page | Lacks the granularity to represent these accurately | Required to map how the entities actually connect |
| Dynamic data tied to frequently changing site functionality | Risks drifting out of sync as content updates | Builds markup that tracks the underlying content directly |
| Custom or non-standard content structures | Forces the content into the nearest generic template | Describes what the page actually is, not a template match |
What a Plugin Is Built to Handle
A plugin runs on templates. It spots the common patterns (a business listing, a standard article, a single product) and fills in the matching schema type automatically.
What a Developer Builds That a Plugin Can't
A developer builds markup around what the page actually is, not the closest template to it. That gap is where custom entity relationships, nested data, and dynamic fields live. Practices needing that level of accuracy typically turn to professional AEO implementation rather than a generic plugin. There is more on professional AEO implementation if this is the part that matters to you.
Reading the Google and Schema.org Rulebook Correctly
A plugin or a developer can execute markup perfectly and still misread what the rules actually say. The standards carry just as much risk as the code does.
What Google's Structured Data Guidelines Actually Require
Google's own guidance ties eligibility to indexing and snippet display, not to how elaborate the markup gets. So a market that equates more schema with more authority has misread the rulebook entirely (kinda the whole problem). Reading it right means knowing what it doesn't ask for, too.
Why Markup for Visible Content Only Matters
The earlier point about annotation errors traces back to this exact gap. Guidelines get skipped, not misunderstood, when markup describes content a visitor never sees on the page. That mismatch is a guideline violation, not a technical nuance. Google's structured data guidelines say markup must be a true representation of the page content, and not to mark up content that is not visible to readers of the page.
Putting Markup to Work — A Staged Implementation View
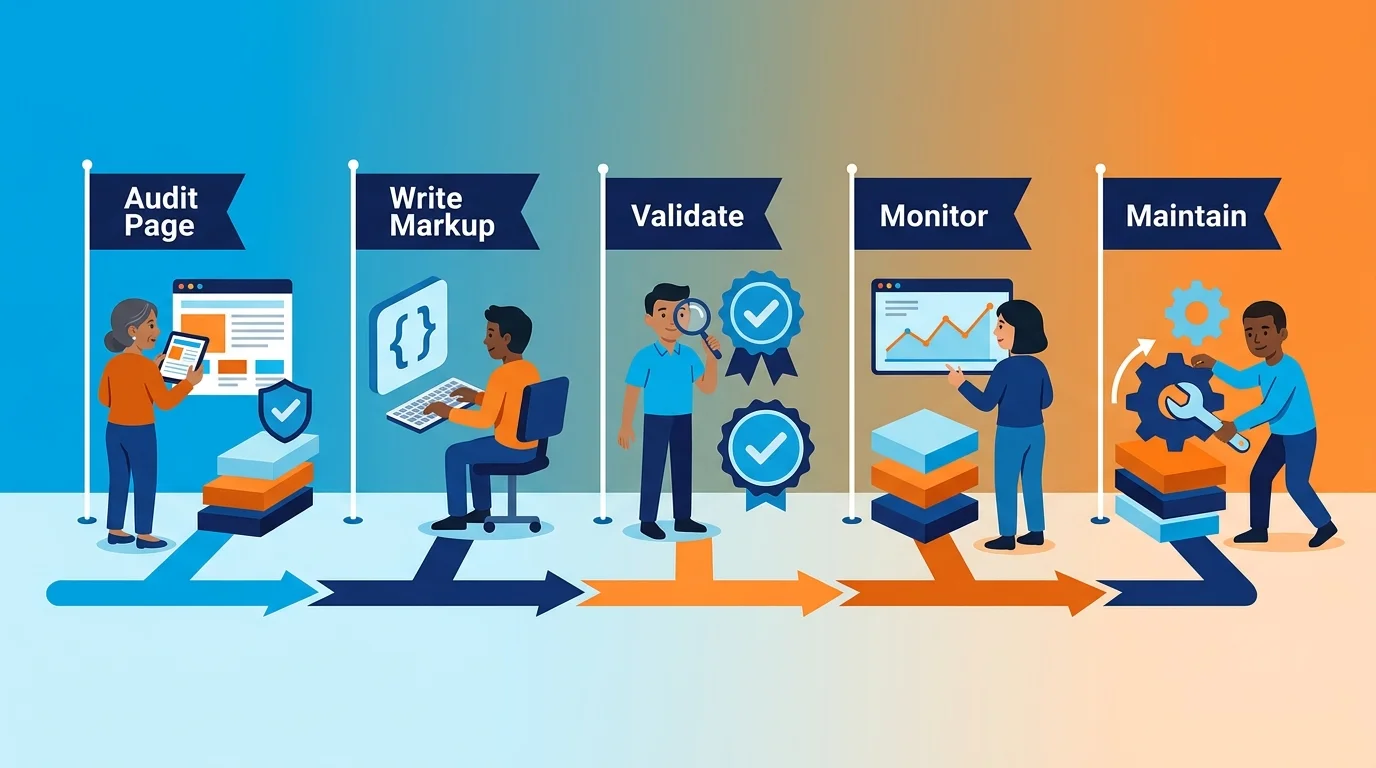
Architecture and rules don't mean much until the markup actually ships. So the real test is sequence: audit first, write the markup second, then validate and maintain it on a schedule. Skip any stage and the same drift from earlier walks right back in.
| Implementation Stage | What Happens | Who Typically Owns It |
|---|---|---|
| Content Audit | Every page is reviewed for entities, relationships, and data points actually present, rather than assuming a template fits. | Staff can run this stage using a documented checklist, since it requires familiarity with the content rather than coding skill. |
| Markup Drafting | Structured data gets written to match what the audit found, choosing templated schema for simple pages or custom markup for layered ones. | Staff and plugins can cover standard templated cases; a developer takes over once nesting or multiple interrelated entities are involved. |
| Validation | Draft markup is checked against the live page to confirm every declared field matches visible content and resolves without errors. | A developer typically owns this stage on complex builds, since silent failures are easy to miss without technical review. |
| Ongoing Maintenance | Markup is re-checked on a recurring schedule as content changes, new services get added, or page structure shifts. | Ownership can sit with staff for simple updates, but a developer should be looped in whenever the underlying page logic changes. |
Auditing the Page Before Any Markup Is Written
Before anyone writes a line of code, every page needs an honest inventory of what's actually on it. That means listing the real entities, relationships and data points on the page, not the ones a template assumes are there. The audit is what catches the gap between visible content and what the markup would have to declare.
Validating, Monitoring, and Maintaining Markup Over Time
Let's keep it real: markup isn't a set-it-and-forget-it install. It needs regular checks against the live page to catch the drift that creeps in as content changes. A re-check schedule is what keeps the translation layer fluent instead of letting it quietly go stale.
Frequently Asked Questions
The architecture call matters more than any single mechanical detail. But you still want the specifics answered straight, so here they are.
What are the most common errors when implementing schema markup manually?
Missing required fields, broken syntax and markup describing stuff that's not on the visible page top the list. Mismatched entity relationships come a close second. They show up most on pages covering several related services.
Can a marketing team member without coding experience use a plugin for all schema needs?
For templated, common page types? Yes. Once a page needs custom entity relationships or dynamic fields, the plugin's templates stop matching what the page actually is.
What is the risk of having incorrect or outdated schema on a website?
Incorrect or outdated structured data mislabels a page to any system reading it. The page does not just lose a feature; it loses its claim to being accurately described at all.
How long does it take for Google to recognize new structured data after it's added?
No fixed window exists, and no source in this discussion specifies one. Markup eligibility depends on the page being indexed and shown with a snippet, not on a recognition countdown.
Is it better to have no schema at all than incorrect schema?
No schema at all leaves a page ineligible for the richer labels structured data provides, but it is not actively wrong. Incorrect schema actively mislabels the page, which is the worse failure.
How does structured data connect to inclusion in AI Overviews or AI Mode?
That eligibility question was answered earlier: indexing and a visible snippet are what unlock a supporting-link spot, not the markup itself. Structured data's role is narrower. It sharpens how precisely a qualifying page gets described once it already clears that bar.
The Bottom Line
So here's where it lands: schema markup is still a translation layer. The only real decision is who you trust to write it fluently.
A clinic's staff and plugins can handle simple, templated pages just fine. Custom, layered or constantly changing markup needs developer-level precision, because a broken translation fails silently and nobody notices until the citations never show up.
A page that mistranslates itself to a machine reader never gets cited, no matter how strong the content behind it reads to a person. Being a listed address in old-school search work is no longer the goal worth optimizing for. Being the cited authority inside AI-generated answers is, and that starts with deciding, deliberately, who writes your markup: start with an AI Visibility Check.