
What a Practice's Reputation Actually Means to an AI Engine
An entity record is what an AI engine reads before it ever reads a star rating. It is the sum of a practice's name, location, credentials, and specialties, cross-checked against every place that information appears. For a professional practice, reputation isn't just about star ratings; it's about being seen as the definitive, trustworthy answer to a patient's problem.
Here's the thing: the shift from traditional search results to AI-generated answers has fundamentally changed how a practice's reputation is built and measured online. Holding a spot in classic search listings used to be the proof of authority. Now citation is the proof. Anyone studying this shift can find a complete comparison of boutique and agency models for clinics that lays out how that work diverges by firm type.
Why Treating Reputation Like a Listing Breaks Down
Chasing a listing spot is the wrong game now. It means fighting for a position instead of building a record, and that habit falls apart the second an AI engine answers the question instead of showing a results page.
You can claim a listing, dress it up and walk away. An entity record has to be right everywhere, all the time, or the citation simply never happens.
The Volume Model Mass-Production Shops Run On
Mass-production marketing shops live and die on volume: more articles, more directory submissions, more listings touched every month across every client on the roster. Underneath it all sits one assumption (and it's a shaky one): more content equals more visibility.
That assumption broke the moment being cited replaced being ranked as the outcome that counts. And that's how mass-production shops put clinic standing at risk: identical output stamped out at scale instead of fixing the specific data gaps one practice actually has.
Why the Volume Model Erodes a Clinic's Own Record
Let's keep it real: scaled content cranked out to hit a quota runs straight into how search systems police spam. Google's own spam policies name doorway pages, scaled content abuse and link spam as practices it watches for, and they say plainly it may act against any spam pattern it detects.
Google's documentation says Google's spam policies may cover practices such as doorway abuse, scaled content abuse, and link spam, and Google may act against any type of spam it detects. Meanwhile, some agencies still grade themselves on keyword position tracking, a number that says almost nothing about whether a system cites the practice at all.
How Citation Eligibility Actually Gets Measured
Citation eligibility gets measured, not guessed at. A page either clears the bar or it doesn't get cited (no partial credit, no participation trophy).
Google's documentation says a page must be indexed and eligible to be shown in Google Search with a snippet to be eligible as a supporting link in AI Overviews or AI Mode, with no additional technical requirements. Now… this part matters: that standard is narrower than most practices assume.
| Signal | What It Measures | Why an AI Engine Reads It |
|---|---|---|
| Indexing Eligibility | Whether a page is indexed and able to appear in Google Search with a snippet | An AI engine will not cite what it cannot already surface, so this is the baseline filter before anything else is read |
| Entity Consistency | Whether a practice's name, location, credentials, and specialties match across every directory and data aggregator | Conflicting records signal an unreliable entity, so an AI engine favors a source that resolves to one consistent answer |
| Review Sentiment | What reviews actually say about a practice, not just the star count attached to them | Sentiment gives an AI engine context a number alone can't, so it reads tone and detail alongside the rating |
| Source Authority Signals | Whether published content demonstrates verified credentials and genuine subject expertise | A citation carries reputational weight for the engine making it, so it favors sources that show demonstrable standing |
| Content Origination Pattern | Whether material is built around one practice's specific gaps or produced at volume across unrelated clients | Scaled, repetitive content resembles the patterns spam policies watch for, which works against citation rather than toward it |
Building the Entity Record a System Can Verify
An entity record is built from structured data, not decoration. Name, location, credentials, and specialties have to match everywhere a system checks them, with no exceptions and no stale copies left standing.
Where the Knowledge Panel Fits in That Architecture
Google's knowledge panel is one visible piece of that architecture. It's not the whole thing. Google's own explainer on knowledge panels says many knowledge panels can be claimed by the subject they are about, such as a person or a company, and local businesses can manage elements such as opening hours and contact phone numbers through a separate claiming process operating through Google My Business.
Claiming the panel is a starting point, not a finish line. A practice that stops there still leaves the underlying data unverified everywhere else an algorithm might look. Authority built this way compounds because the practice owns the record outright; attention rented from a results page expires the moment the next update lands.
Claiming and Maintaining the Record Over Time
So keeping that record right never really ends. That's why practices lean on AI search optimization services built to fix one practice's specific data gaps, not to stamp one template across a whole roster. A side-by-side look at boutique and multi-client models shows why fixing data gaps one practice at a time looks nothing like stamping the same fix across a roster of unrelated clients.
Sequencing the Work So Nothing Gets Cited on a Broken Foundation
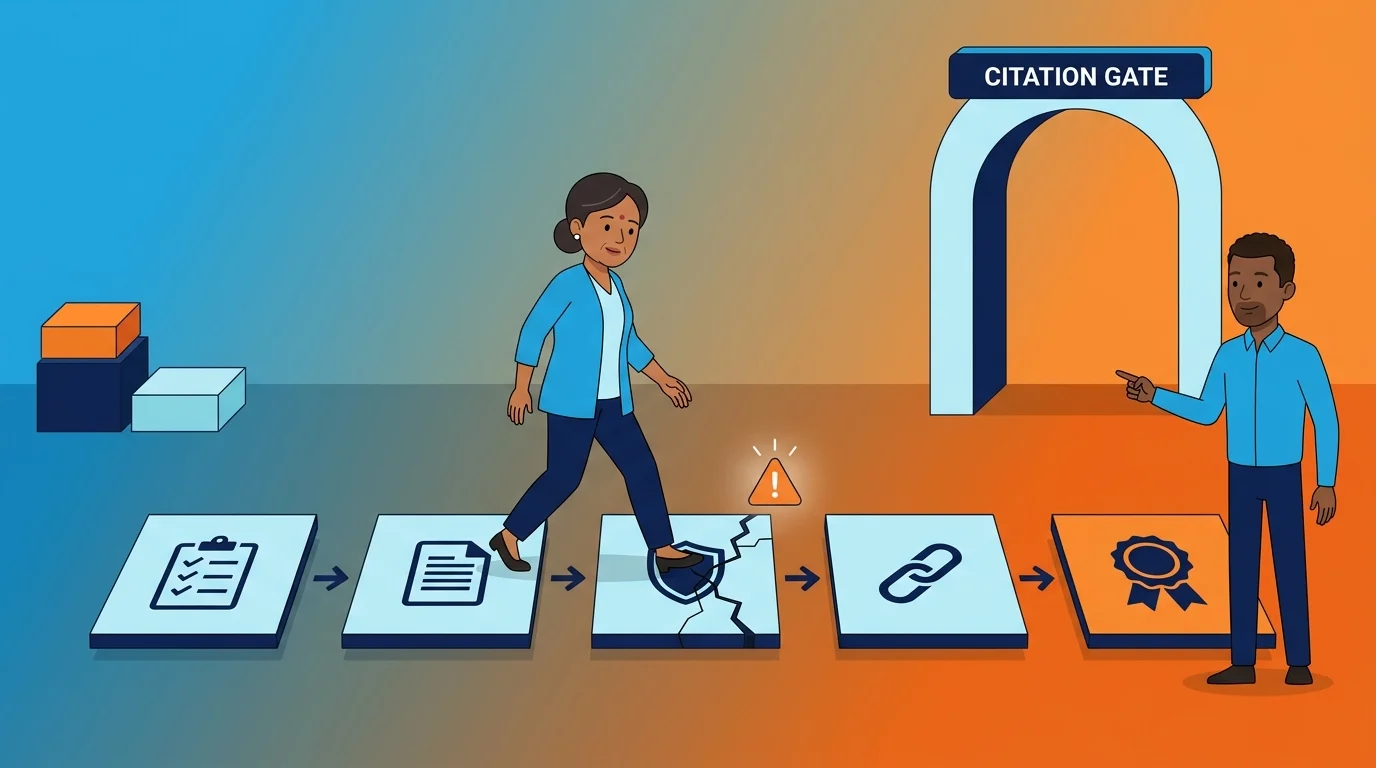
Entity work has a sequence, and skipping ahead in it produces exactly the inconsistencies this article has already named. Structured data gets corrected first, review sentiment and content come after, never the reverse.
| Step | What Gets Verified | Why It Comes Before the Next Step |
|---|---|---|
| Entity Verification | Name, location, credentials, and specialties checked against every directory and dataset a practice touches | Content published before this step just repeats whatever inconsistency still exists underneath it |
| Consistency Correction | Conflicting or outdated records found during verification get corrected everywhere they appear, not just in one place | A record that agrees in one directory and contradicts itself in another still fails the trust test an algorithm applies |
| Review Sentiment Alignment | Existing review language checked against the corrected entity record so both tell the same story | Sentiment read against a still-inconsistent record only amplifies whichever version of the data is wrong |
| Authority Content Publication | Content built to demonstrate expertise, written only once the record underneath it holds together | Publishing ahead of correction buries the inconsistency rather than resolving it |
| Citation Candidacy Review | The finished record and content checked against indexing and eligibility standards before being treated as citable | Submitting for citation before this review risks a system citing a source that still contradicts itself somewhere |
The Order Operations Follow Before Any Record Gets Submitted for Citation
The order starts with verifying name, location, credentials, and specialties against every directory and dataset a practice touches. Only once those records agree does content built to demonstrate expertise get published and submitted for consideration as a citable source. Publishing ahead of that correction just buries the inconsistency under new material instead of fixing it.
What Breaks When a Step Gets Skipped
Skipping the verification step doesn't delay the result. It produces a citation built on a record that still contradicts itself somewhere. Rented attention works this way by design: it borrows a position instead of fixing the data underneath it, and that position expires the moment the data gets checked again.
Frequently Asked Questions
A few mechanical questions sit underneath everything covered so far. Here are direct answers.
What does entity validation mean for a clinic's online record?
It means a practice's name, location, credentials and specialties match everywhere a system looks. No stale copies. No directories contradicting each other.
What specific technical signals do AI engines check to assess a practice's reputation?
Google's documentation names one requirement: indexed and snippet-eligible.
How does a templated marketing approach damage a clinic's entity record?
It runs identical tactics across unrelated clients instead of fixing one practice's actual data gaps. So the inconsistencies stay put. They just get buried under fresh content.
How long does it take for a verified entity record to show up in AI-generated answers?
No fixed timeline applies here, and any promise otherwise isn't credible. Citation depends on correcting the underlying record, not on a calendar.
What is a knowledge panel and how does a business claim one?
A knowledge panel is a visible summary of a verified entity, claimable by the person or company it describes. Local practices work through a separate process that covers details like hours and phone numbers rather than the panel itself.
How do conflicting business data listings affect citation eligibility?
Conflicting listings tell a system the entity can't be trusted yet.
The Bottom Line
Here's where it all lands: your practice's reputation lives as an entity record now, not a listing. Own it outright and it compounds. Rent it from a results page and it expires the second that page changes.
A boutique firm builds the record, while a mass-production shop babysits the listing. One earns a citation an AI engine actually trusts. The other buys attention that vanishes with the next update, no matter how many articles or directory submissions are stacked behind it.
The practices that get cited are the ones whose data was corrected before it was published, not after. That is the standard this article holds to, and it starts with an honest look at where a practice's own entity record stands today — the kind of look delivered through an AI Visibility Check.