
The Metric That Stopped Mattering: What Actually Happened to Word Count
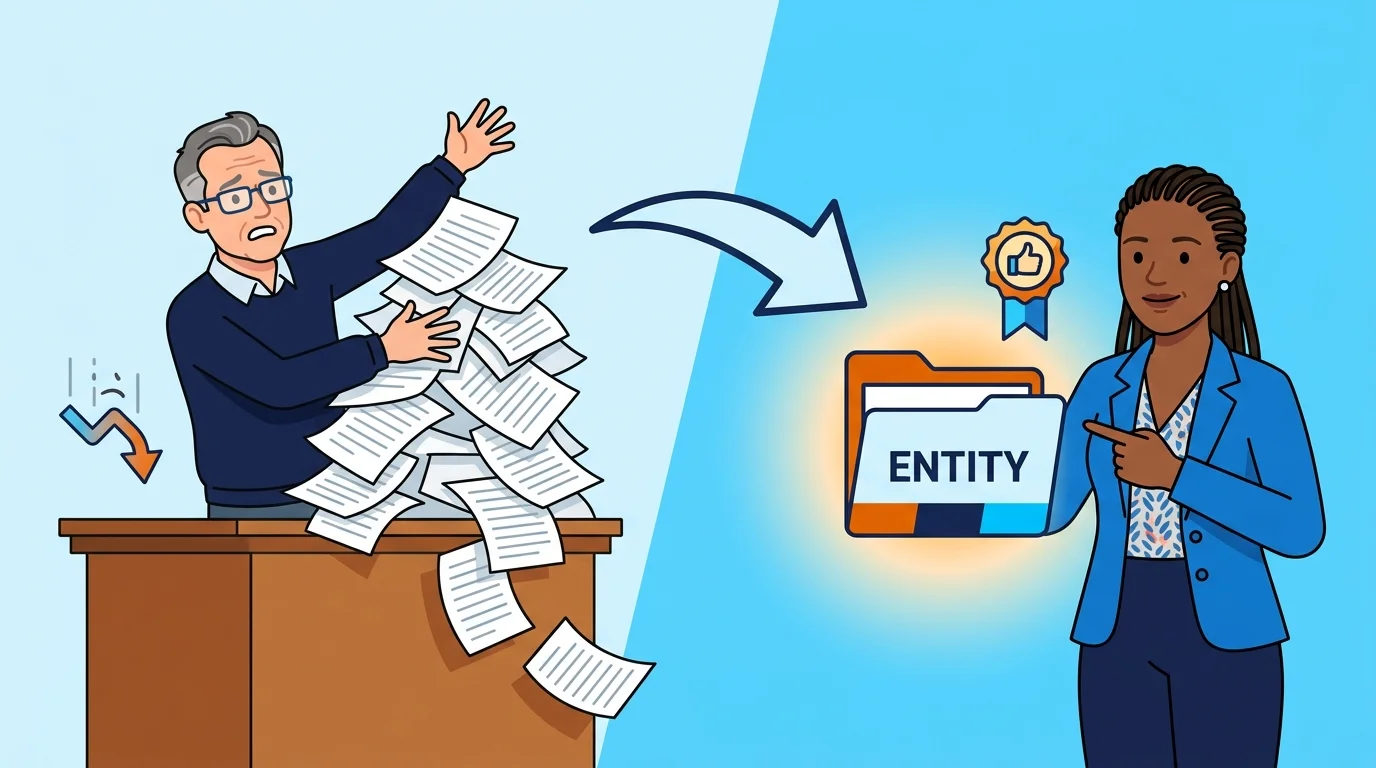
Word count had a good, long run. For decades, longer meant better — more words got treated as a stand-in for expertise, thoroughness, and authority, and nobody really questioned it.
That assumption is exactly what this shift breaks. Regression analysis has found no statistically significant relationship between ranking position and word count — meaning length alone was never doing the work everybody credited it with.
So what was word count actually measuring? Mostly effort, not clarity. A ten-thousand-word page and a five-hundred-word page can carry the exact same entity, and only one of them might bother to mark its boundaries.
Here's the thing about a proxy metric: it works right up until the system it was measuring changes underneath it. Local businesses feeling this shift firsthand can watch it play out in what standalone AEO content boundaries mean for a local business, where entity-first logic replaces length as the signal that actually counts.
| Old Assumption | What The Data Actually Shows | What It Means For Content |
|---|---|---|
| Longer content signals more thoroughness and authority. | Regression analysis shows no statistically significant relationship between ranking position and word count. | Length stops being the target. Structured entity boundaries become the thing worth building toward. |
| A high word count proves a page covered a topic in depth. | Depth was never measured by length. It was measured by whether an answer engine could parse and classify what the page contained. | Coverage gets demonstrated through clearly defined entities and their relationships, not through padding a page to a target length. |
| Writers should aim for a minimum word count to satisfy ranking systems. | Answer engines parse structure, not volume. A short page with explicit entity boundaries can outperform a long one without them. | Structured semantic content engineering replaces the word count target as the actual objective for visibility. |
Why Long Content Stopped Being a Signal
Long content stopped being a signal the second answer engines stopped reading start to finish. Length was never the thing getting rewarded.
It was a correlation mistaken for a cause. Thorough pages tended to be longer, so length quietly took credit that depth and clarity actually earned.
Now that mistake shows up in the data itself. The missing statistical link between ranking position and word count, confirmed through published research data, is the settled proof: the old proxy never measured what the industry assumed it did.
What an AI Engine Is Actually Doing When It Reads Your Page
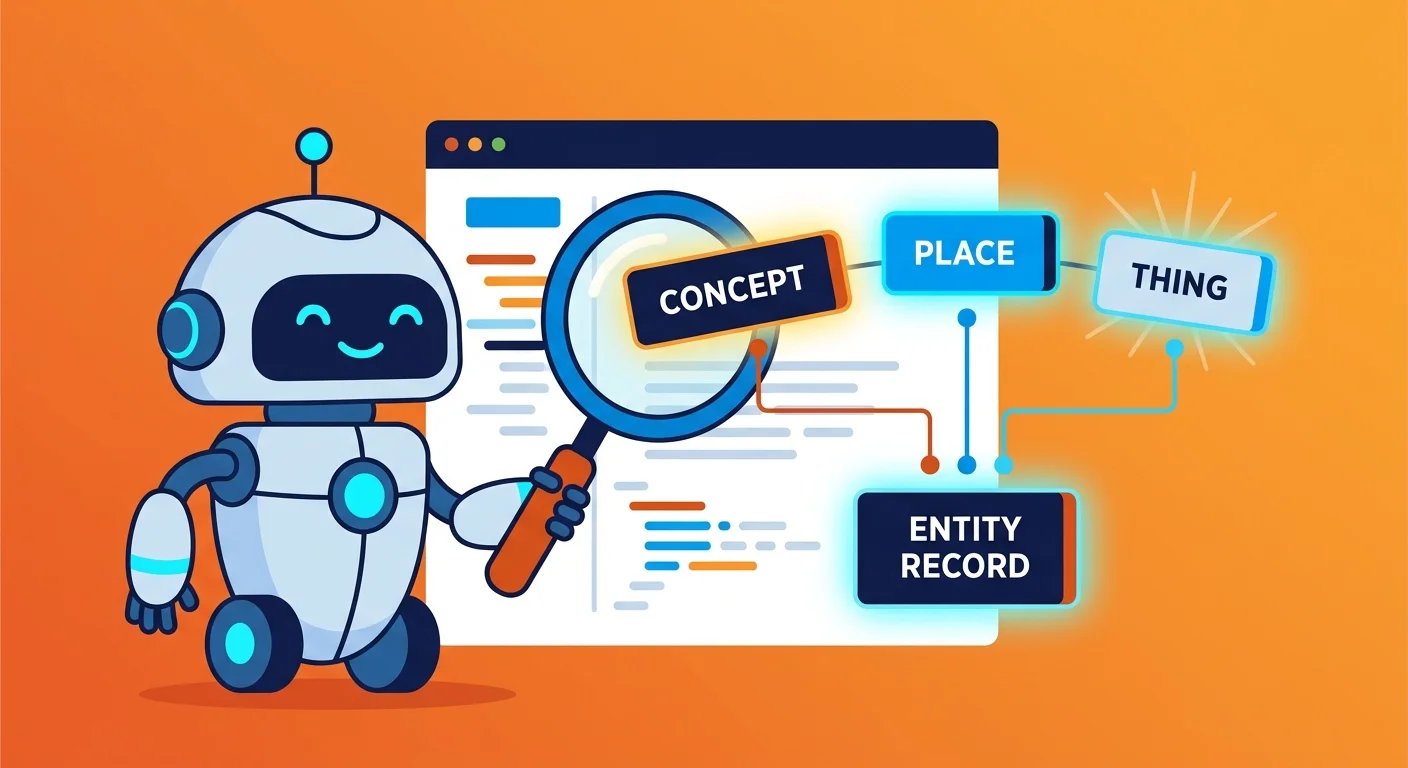
So what does an AI engine actually do the second it hits your page? It parses. It doesn't read prose the way you do, sentence by sentence, soaking up tone and nuance on the way through.
It's built to pull structured meaning off the page and toss the rest. That's a completely different job than reading, and it changes what counts as good content.
Here's the thing about parsing: it either finds a clean data structure or it doesn't. When it doesn't, the machine is stuck guessing. And guessing is where your visibility quietly disappears.
Entities, Defined: The Unit AI Engines Actually Count
The real unit an AI engine counts is the entity, not the word. A distinct, well-defined concept, person, place, or thing only counts as one when a machine can spot it and tie it to related information without confusion.
That definition matters because it throws out almost everything word count rewards. Padding, filler transitions, restated ideas — they pile on length without handing a machine one new entity to grab.
This is the change sitting underneath the whole shift. Keyword matching used to score how often a phrase showed up. Entity understanding scores whether the actual thing that phrase points to has been made legible to a machine.
Where Ambiguity Breaks Machine Understanding
But entities aren't automatically legible just because you know what you mean. Ambiguity is where machine understanding breaks, and it breaks for reasons that have nothing to do with sloppy writing.
Research on expert-annotated named entity recognition datasets across three language varieties found that text ambiguity and artificial guideline changes were the dominant drivers of disagreement among trained human annotators. So if skilled reviewers working from the same text can't agree on the entities, as documented in research published through the ACL Anthology, an automated system staring at that same unstructured prose has no better odds.
That's the whole case for building the boundary in first, instead of praying the machine infers it right. Teams that want a concrete read on how this plays out can see the audit process laid out in auditing how standalone pages actually perform inside conversational search results, which walks through exactly what conversational engines reward once word count is off the table.
How Schema Markup Draws the Boundary Lines
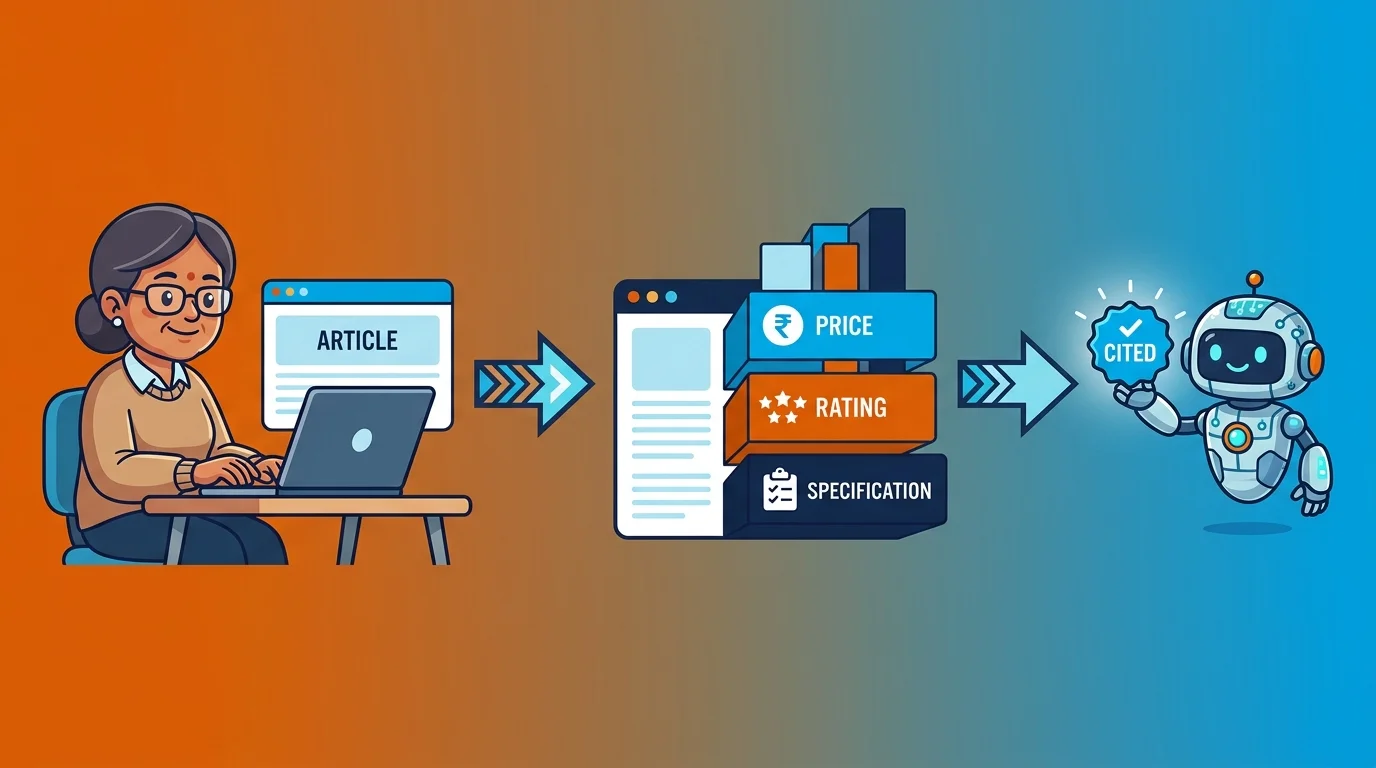
So here's the mechanism that kills the guessing. Schema markup is code you embed on a page that names an entity in a vocabulary a machine already knows — no inference required.
Instead of an AI system wondering whether a block of text is a service, a person, or a product, schema just says so. That one declaration turns a loose paragraph into a labeled folder the machine files correctly on the first pass.
But not every schema type pulls its weight. Generic markup announces that an entity exists without saying what makes it distinct — and that gap is exactly where citation rates start splitting apart.
| Schema Approach | AI Citation Rate | Why The Gap Exists |
|---|---|---|
| Generic Markup Only (Organization, Article, BreadcrumbList) | Substantially Lower | Declares that an entity exists but attaches no concrete attributes, leaving the machine with a label and nothing to extract. |
| Product or Review Schema With Populated Attributes | Substantially Higher | Names the entity and supplies pricing, ratings, or specifications, giving the AI system a fact it can quote with confidence. |
| Partial Schema With Incomplete Fields | Inconsistent | Marks the boundary but leaves required attribute fields blank, so the machine cannot tell whether the entity is fully described or half finished. |
| No Structured Data | Lowest | Forces the AI engine to infer the entity from prose alone, reintroducing the exact ambiguity structured data exists to remove. |
The Concrete-Attribute Advantage
Look at what different schema types actually declare and the gap jumps out. Pages using Product or Review schema packed with concrete attributes — pricing, ratings, specifications — got cited by AI systems like ChatGPT and Gemini at 61.7%, against 41.6% for pages leaning on generic types like Article, Organization, or BreadcrumbList.
That gap isn't decoration. It's the difference between an entity boundary with substance inside it and one that's just a label with nothing attached — a distinction the underlying published research data pulls straight from citation behavior, not assumption.
Here's the thing about concrete attributes: they hand a machine something to extract, not just something to nod at. A price, a rating, a spec — each one is a fact the AI engine can quote with confidence, which is exactly why generic Organization or Article markup falls short. This is the line separating commodity content packages from structured semantic content engineering, and it's why entity boundaries built only halfway still leave visibility on the table.
Where Entity Boundaries Show Up Beyond the Search Box
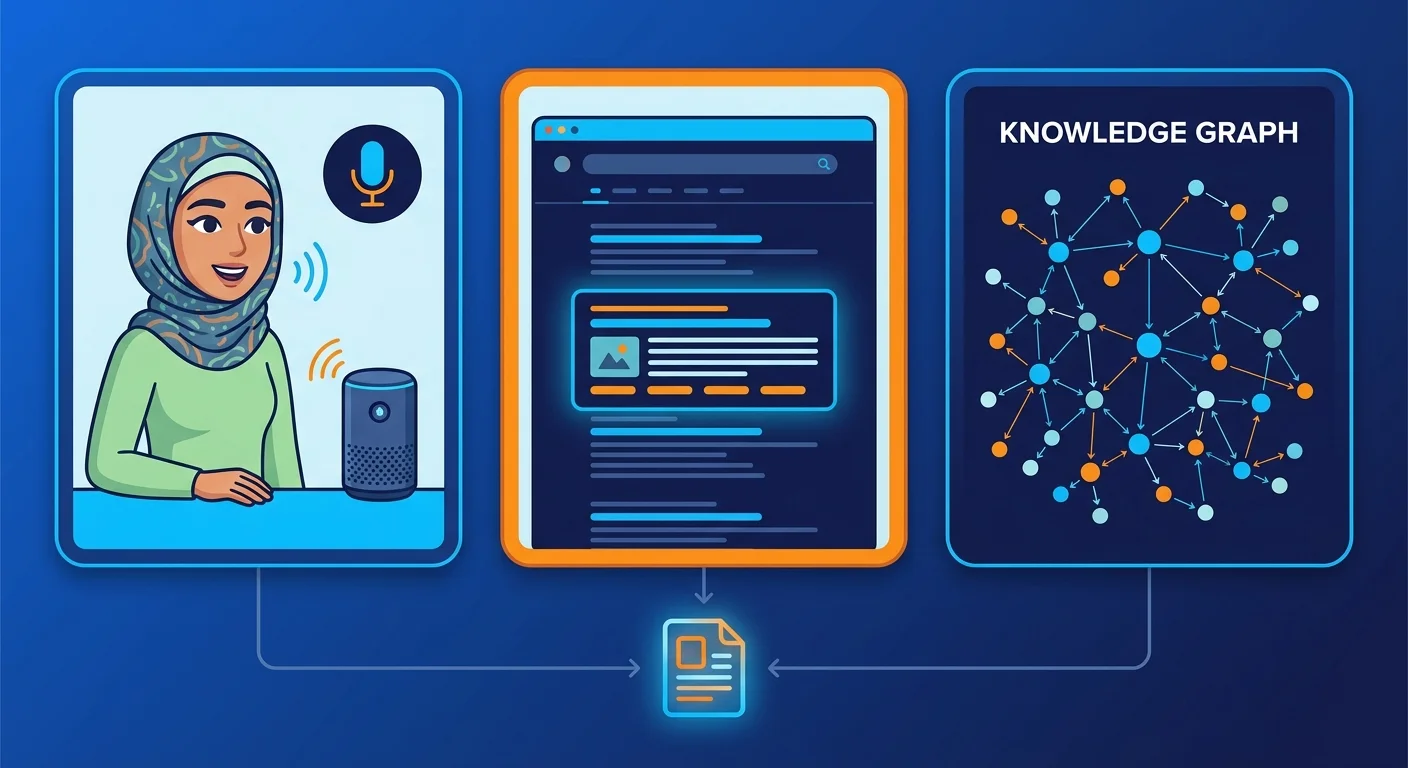
Entity boundaries don't clock out once a page ranks. They keep working everywhere a machine meets that content next — a voice assistant reading a snippet aloud, a knowledge panel yanking a fact into view.
So the search box was never the only surface that mattered. It was just the easiest one to measure, which is part of why word count hung around as long as it did.
Look at where AI actually serves up answers today and the pattern repeats. Structured entities travel clean across surfaces; unstructured prose gets reprocessed, or skipped, at every new stop.
Voice Assistants and the Speakable Layer
Voice search has no scroll bar. No visual hierarchy to lean on either. A smart speaker either has a clean fact to read aloud or it's got nothing worth saying.
Google Assistant shows this off directly with its use of speakable structured data on news queries. Ask about a specific topic on a smart speaker and the assistant returns up to three articles from around the web, playing audio for the sections marked with that structured data.
That whole mechanism only works because the content was pre-labeled. A long, gorgeous paragraph gets you nothing if there's no structured marker telling the assistant which section is speakable.
The Knowledge Graph as the Destination
Here's the thing about the knowledge graph: it isn't built from articles. It's built from entities, each one linked to related entities through defined relationships — not shared keywords.
The scale of that thing is worth sitting with. The Knowledge Graph holds millions of entries describing real-world people, places, and things, and every single one exists because somebody, somewhere, drew a clean boundary a machine could confirm — a scale Google's documentation lays out directly.
An entity earns its spot in that graph by being unambiguous, not by being long. That's exactly what millions of entries describing people, places, and things confirm, a fact Google Search Central documents plainly, and it's the same bar your content should clear before publication, not after.
Getting a page's own markup to actually connect with that graph is a separate technical step, one covered in how a standalone page's markup should connect to a site's existing schema — because a well-formed entity that never links back to the rest of a site's structure still leaves value on the table.
Auditing Your Own Content for Entity Boundaries
So what does this look like on a page someone owns right now? Not in theory. In the raw file sitting on a server today.
Here's a fast check. Pull up any page and ask whether a machine reading it cold could name every entity on it without guessing.
If the answer's fuzzy, the page is still loose paper. It might read beautifully to a person and still hand an AI engine nothing but ambiguity.
| Audit Checkpoint | What Weak Structure Looks Like | What Strong Structure Looks Like | Fix Priority |
|---|---|---|---|
| Naming Consistency | The same service, person, or product gets referenced with three or four different phrasings across a page, leaving a machine to guess whether they refer to one entity or several. | One canonical name is used every time that entity appears, with variations linked back to it explicitly rather than left implicit. | High — this is the cheapest fix and the one most likely to break entity recognition if ignored. |
| Schema Depth | Generic markup such as Organization or Article is dropped onto a page and treated as complete, without a single concrete attribute a machine can extract. | Markup includes concrete, specific attributes tied directly to the entity being described, giving a machine something to quote rather than just acknowledge. | High — shallow schema is the most common reason a page ranks but never gets cited. |
| Cross-Page Linking | An entity is labeled correctly on one page but never connected to how it relates to anything else the site publishes. | The entity links outward to related entities across the site, so a machine can place it inside a larger structure instead of holding it in isolation. | Medium — valuable once naming and schema depth are already solid. |
| Prose-to-Structure Ratio | Long paragraphs carry the meaning while structured markup is treated as an afterthought bolted on after publishing. | Structured data carries the core facts first, with prose used to explain context and nuance around what the markup already states. | Medium — reorders priority without requiring a full rewrite. |
The Three Places Boundaries Usually Break
Boundaries tend to break in the same three spots, over and over, no matter the industry.
First is naming. A page names a service, a person, or a product three different ways across three paragraphs, and a machine has no reason to assume those phrasings point at the same thing.
Second is markup that exists but says nothing. Generic Organization or Article schema gets dropped on a page and called finished, when it never described one concrete attribute worth extracting.
Third is isolation. An entity gets labeled right on one page and never linked to how it relates to anything else on the site, which leaves a machine holding a fact with nowhere to file it.
Frequently Asked Questions
A few questions keep surfacing once that walkthrough lands. Here are the straight answers, no runway.
What is a structured entity boundary in the context of AI?
It's a piece of content — a service, a person, a product — defined clearly enough that a machine can name it and link it to related information without guessing. A structured entity boundary is what turns a vague reference into a fact an AI engine can lift.
Why is word count a less reliable metric for AI engines than clearly defined entities?
Word count measures effort, not clarity. And whether a page ranks has no reliable tie to how long it runs. So a page can go on forever and still say nothing a machine can confidently parse.
How does schema markup help AI engines recognize entity boundaries?
Schema markup states an entity's identity in code instead of leaving a machine to infer it from prose. That declaration is what lets an AI engine file a page right on the first pass instead of skimming for clues.
Can an article with a low word count but strong entity structure outperform a longer article?
Yes, and it isn't close. A short page with clean entity boundaries hands a machine something concrete to cite. A long page full of ambiguity hands it nothing worth extracting.
What are the first steps to start defining entities in existing content?
Start by naming every entity on the page the same way, every time. Then attach concrete attributes instead of generic labels. After that, connect each entity back to how it relates to the rest of the site's existing markup.
How do knowledge graphs use the entity information from a website?
A knowledge graph absorbs the entity data on a page and links it to everything it already knows about that entity. The cleaner the boundary a page draws, the more confidently the graph can place it among related people, places, and things.
The Bottom Line
So here's the bottom line. Word count was never the thing getting measured. It was a proxy for effort, and proxies die the second the system reading them changes.
Structured semantic content engineering doesn't treat that shift as a threat. It treats it as the actual job. Clear entity boundaries are what let an AI engine parse a page with confidence instead of guessing at it — and confidence is what gets a page cited, quoted, and surfaced across every conversational engine now standing between a business and the people looking for it.
So look at the page in front of you right now. Is it a labeled folder an AI engine can grab and file without a second thought, or is it still a loose pile of well-written paragraphs waiting to be sorted? Find out where your content actually stands with a free AI visibility check.