
What Machine-Readable Data Actually Means On An Older Platform
Here's the thing: how a site looks and how its data is structured are two different animals, and mixing them up is the first mistake worth killing. Machine-readable data is information formatted for software to parse — search crawlers, generative AI systems, anything reading a page without human eyes. It doesn't care one bit what the page looks like.
A theme from a decade ago tells you nothing about whether the content underneath is structured (and that's exactly the distinction operators researching AI visibility keep missing). Nailing it matters more than the redesign question itself, especially for clinic owners weighing a rebuild versus new content who assume a new build is the one lever they've got.
Why Appearance Gets Mistaken For Disqualification
Plenty of businesses figure an older website is an automatic disqualifier for modern search. That's confusing aesthetics with data accessibility, plain and simple. The logic treats a dated template as proof the code underneath can't carry structured facts, and it can.
That assumption is backwards. The focus has shifted from how a platform renders a page for humans to how cleanly it hands factual data to an AI, and a system reading a page for citation never once grades the storefront's visual polish.
When a Rebuild Comes First, and When It Can Wait
New content and structured data can help on an existing site, old platform or new one. Still, a full rebuild onto the iTech Valet Authority Platform, built for AI visibility, with a design update, is usually the recommended path. Keeping the current site is the fallback: iTech Valet reworks it and rewrites the sales copy, case by case.
Some folks call AI visibility traditional search optimization with new vocabulary, and that frame's wrong, but even they'd admit the mechanism rewards clean, accurate data over surface design. So a practice weighing that trade-off should get clear on what fixed templates and weak metadata mean for citable content before choosing between a rebuild and keeping the current site.
How Structured Data Adoption Actually Looks Across The Web
Adoption data settles the aesthetics argument fast: the first Web Data Commons crawl in 2010 found structured data on just 5.7% of the webpages it examined. Findings from Web Data Commons (University of Mannheim) show structured data was found within 50.6% of the webpages examined in the October 2023 crawl, compared with 5.7% in the first 2010 release. Here's the kicker: that growth happened across the entire web.
So before anyone decides the fix requires a rebuild, the smarter first move for diagnosing an underperforming page is recognizing site issues that block AI visibility.
| Crawl Year | Share Of Webpages With Structured Data | What Changed |
|---|---|---|
| 2010 | Minimal presence | Structured data was a niche implementation known mostly to early adopters experimenting with new markup standards. |
| 2023 | Majority presence | Structured data had become a mainstream baseline practice across webpages. |
When Keeping the Current Site Makes Sense
Keeping the current site makes sense when a practice must keep it and its platform can still carry a clean, structured data layer. Then iTech Valet reworks the site and rewrites the sales copy, case by case. Either way, the goal is a citation, not a listing. Holding a spot in classic search listings was always a stand-in for visibility, never the thing itself.
And that stand-in quits working once answers replace links. Per Pew Research Center, just 1% of visits to pages with an AI Overview may result in a click to the cited sources. That gap between showing up and getting clicked says it all: the listing was never the asset worth chasing.
What Gets Lost When A Business Chases A Listing Instead Of A Citation
Chasing a listing instead of a citation means optimizing the wrong layer. The business polishes the storefront and leaves the data layer a mess. Then it wonders why generative systems never surface a word of its content.
A practice can hand the structuring work off entirely through done-for-you AEO services before deciding whether a rebuild comes first.
How An Older Platform Gets Read By Crawlers And AI Systems
A crawler grabs the raw HTML response and parses whatever shows up.
So structured data sitting right inside that HTML response is readable instantly, no extra step. That's the architectural edge an older, simpler platform often carries without anybody planning for it (funny how that works).
Static HTML Versus JavaScript-Dependent Rendering
Static HTML delivers every element in the initial server response, structured data included. A JavaScript-dependent page often builds that same content after the page loads, inside the browser, which adds a rendering step before anything is readable.
Where Sitemaps And Feeds Fit Into The Picture
Sitemaps and feeds do not replace structured data. They point crawlers toward where that data lives.
Per Google's documentation, Google supports the sitemap formats defined by the sitemaps protocol, though submitting a sitemap is only a hint that may not lead Google to download or use it for crawling. Now, a submitted sitemap is a hint, not an order a crawler has to follow. An older platform that keeps its sitemap current still helps discovery, but once the crawler shows up, the structured markup on each page is what gets read and cited.
Placing JSON-LD Without Touching The Rest Of The Site
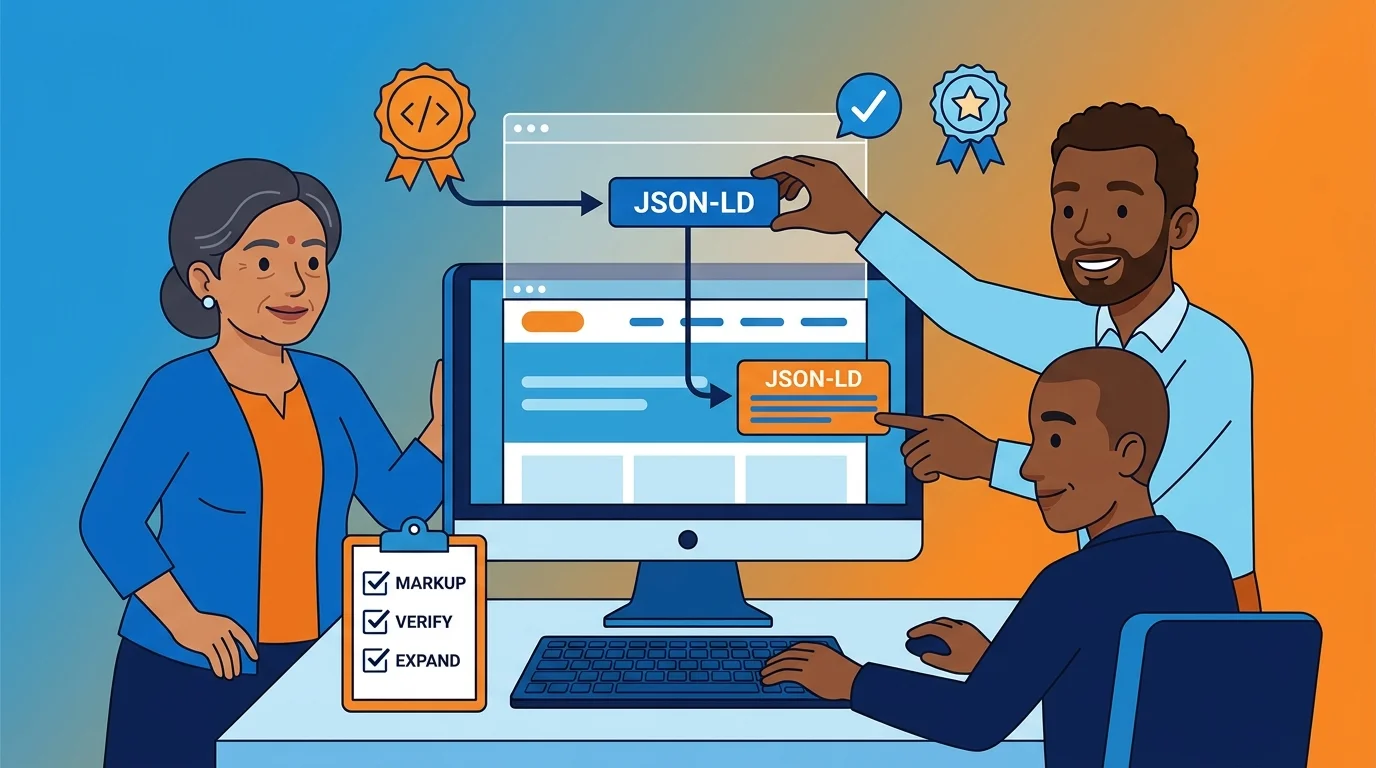
Adding JSON-LD to a legacy page does not touch the template, the theme, or the storefront a visitor sees. It is a block of code inserted into the page head or body, invisible to human readers.
Per Google's documentation, Google's structured data guidelines recommend JSON-LD as the preferred format for marking up pages to be eligible for rich results, alongside Microdata and RDFa. That guidance applies identically to a page built last month or a decade ago.
| Implementation Step | What It Accomplishes | Platform Dependency |
|---|---|---|
| Audit existing content | Identifies entities, facts, and relationships already present on the page that qualify for markup | None — works on any platform, including the oldest legacy builds |
| Draft JSON-LD describing only visible content | Produces markup that matches Google's structured data guidelines and avoids representing content readers cannot see | None — JSON-LD is a code block independent of template or theme |
| Insert the script into the page head or body | Delivers the data layer to crawlers in the raw HTML response, without touching the visible storefront | Low — most content management systems allow a code insertion point without a redesign |
| Validate markup against platform guidelines | Confirms the structured data is both technically correct and a genuine representation of the page | None — validation tools read the code, not the surrounding design |
| Expand the pattern to additional pages | Scales the same low-footprint markup across the site once the first page proves out | None — repeatable regardless of how dated the underlying codebase is |
Sequencing The Work: Markup, Verification, Expansion
The first action is markup: add JSON-LD describing what already exists on the page, nothing invented. Verification comes next, confirming the code validates and matches visible content.
Expansion follows once the first page proves out, extending the same pattern across the site. Google's structured data guidelines say markup must be a true representation of the page content, and not to mark up content that is not visible to readers of the page.
Frequently Asked Questions
The same handful of mechanical questions shows up every time the storefront-versus-data-layer split comes up. Here are the straight answers.
Does my old website's theme prevent me from adding structured data?
Nope. A theme controls how a page looks, not whether JSON-LD can sit in the head. Structured data lives on its own, totally separate from template design.
Is it better to add Schema directly to my HTML or use a separate script?
A separate JSON-LD script is the recommended approach, per Google's own guidance. It keeps markup isolated from template code, which simplifies updates on an older platform.
Can Google properly extract data from a website that doesn't use a modern JavaScript framework?
Yes. A crawler reads the raw HTML response first, and static markup is visible immediately without a rendering step.
How can I test if the machine-readable data on my older site is working correctly?
Validate the markup against Google's testing tools and confirm it matches what a reader actually sees on the page. Accuracy against visible content is the requirement, not the platform underneath it.
What is the single most important type of structured data to implement on a legacy platform?
Organization and local business schema, naming the entity clearly, carries the most weight on a legacy platform. It locks in the core facts an AI system needs before it parses anything else.
What happens if a submitted sitemap is never used for crawling?
Then the page just stays undiscovered through that one signal. A sitemap submission is a hint, not an instruction. Once a crawler shows up some other way, the on-page structured markup still gets read.
The Bottom Line
A chiropractic site's storefront and its data layer were never the same thing. An older platform can wear a dated storefront and still run a clean, fully structured data layer underneath it.
Platform age is cosmetic. Structured data accuracy is functional, and it helps machines read the page.
A rebuild that only fixes the storefront does nothing for a data layer that was never structured to begin with.
So your next move is a check. iTech Valet usually recommends a full rebuild onto the iTech Valet Authority Platform, built for AI visibility, with a design update; if a practice must keep its current site, iTech Valet reworks it and rewrites the sales copy, case by case. If you want a straight read on where your data layer stands, talk it through with us.