
What Actually Breaks When a Website Ages Past Its Architecture
An old site's architecture was built to be found and clicked. AI retrieval systems need something different: facts they can lift cleanly, without guessing which part of a page is true. That gap is the technical debt nobody budgeted for. The shift from a list of links to a direct answer has fundamentally changed the goal of a business website.
AI visibility runs on different mechanics than legacy search optimization ever did, even though the two get discussed in the same breath. Technical debt on a website is no longer just a performance issue; it's an authority liability. A reader researching earning AI citations without a full rebuild will find the gap between patching content and fixing structure mapped out in full.
Why Patching Old Code Can't Fix What AI Crawlers Need
Patching old code treats the symptom, not the structure underneath. Bolt a new paragraph onto a template and the inconsistent markup an AI crawler is trying to parse doesn't budge. The filing cabinet stays sealed (someone just taped a shiny new label on the drawer).
Why Surface-Level Content Edits Fail AI Retrieval
So why does a content refresh fail where a rebuild succeeds? Because content sits on top of infrastructure, and infrastructure decides whether a crawler can reach the content at all. A page serving the wrong server response never gets indexed, no matter how well it reads.
Google's documentation says Google indexes only pages served with an HTTP 200 (success) status code, and error pages are not indexed. Anyone tracking the signs pointing to a rebuild instead of more content spots this pattern fast.
The Content Decay Problem Nobody Patches Away
Here's the kicker: the same shortcut fails at the content layer too, not just in the code. Stale pages don't sit there quietly. They actively mess with retrieval, because old facts parked next to current ones confuse the systems pulling from both.
Ouyang et al. (ACL 2025) report that, in a benchmark, outdated information coexisting in retrieval sources may substantially reduce RAG response accuracy by distracting models from correct information. That means an old page isn't neutral. It's a liability sitting in the same retrieval pool as accurate content. There is more on does an existing website already qualify for AI citations if this is the part that matters to you.
| Retrieval Condition | What Happens to Model Output | Why It Matters for Citation |
|---|---|---|
| Stale page coexists with current page in the retrieval pool | The model weighs conflicting signals and risks surfacing the outdated version as fact | An AI system that cites the wrong answer stops trusting the domain that gave it one |
| Content gets refreshed but structural markup stays untouched | Retrieval systems still struggle to confirm which text maps to which entity on the page | Clean prose wrapped in unclear structure is still too ambiguous to cite confidently |
| Old and new facts about the same offering sit on the same page without clear dating | The model has no reliable way to distinguish current terms from retired ones | Ambiguity reads as risk, and risk gets a source dropped from the candidate pool |
| A business delays resolving decayed content indefinitely | The retrieval layer keeps treating the domain as an unreliable source over time | Each cycle of inaction is a choice to stay unread by the next generation of search |
How Structured Data Becomes the Bridge Between a Site and an AI Answer
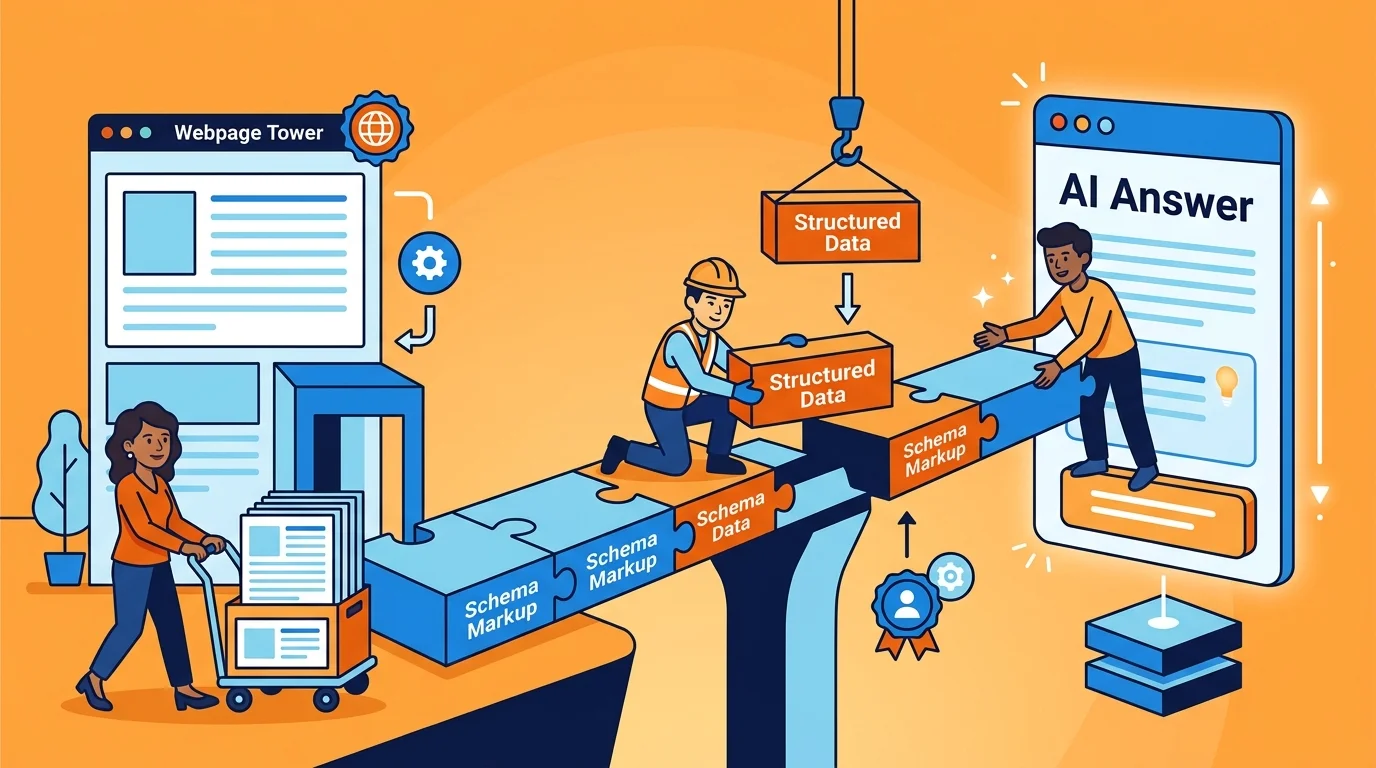
So what actually works? Structured data, the fix no amount of patching can fake, because it labels every drawer in the filing cabinet so a machine knows what's inside before it has to guess. But here's the catch: those labels only help if they match what's really sitting in the drawer.
Per Google's documentation, structured data is recommended as a best practice for AI features because it should match the visible text on the page. The same page also says there's no special schema.org structured data you need to add for AI features. That consistency requirement is the whole point. A page claiming one fact in its markup and showing another in its visible text isn't a bridge to an AI answer. It's a broken one, and no amount of fresh content fixes a label that lies about what's underneath. Getting this right is part of what our AI search optimization services are built around.
| Architecture Element | What It Communicates to AI Systems | Legacy Site Limitation |
|---|---|---|
| Schema Markup Consistency | Confirms that a stated fact matches the visible page text, giving an AI system confidence to lift the claim directly | Legacy templates often carry markup that was never updated when visible content changed, leaving mismatched labels an AI system cannot trust |
| Semantic HTML Hierarchy | Signals which text on a page is the entity, the offer, or the supporting detail, rather than leaving a crawler to guess from layout alone | Older code structures frequently flatten headings and content into generic containers, erasing the hierarchy an AI system needs to separate fact from filler |
| Entity and Attribute Tagging | Labels specific facts, such as a service or credential, so an AI system can cite the detail without re-interpreting surrounding prose | Inconsistent page-to-page templates mean the same attribute may be tagged on one page and missing entirely on another, breaking confidence site-wide |
| Consistent Cross-Page Structure | Lets an AI system apply what it learned from one page to the next, building trust across the whole site rather than page by page | Structures that vary considerably between templates force a retrieval system to re-evaluate every page from scratch, slowing and weakening citation |
Where Legacy JavaScript and Mobile Gaps Quietly Cost You Citations
Two legacy conditions turn that citation failure from theory into reality: old JavaScript frameworks and mobile gaps. Each one breaks a different link in the retrieval chain. But both end in the same place, with an AI system that can't confirm what the page actually says.
Here's the thing: more content never fixes either problem. A site publishing additional pages on top of a framework that hides its own text is adding volume to a structure that still can't be read. More content equals more visibility is a holdover from the old results-page game, not a property of how retrieval systems actually work.
How Legacy JavaScript Frameworks Confuse Modern Parsers
So what's actually going wrong? Older JavaScript frameworks often build the page inside the visitor's browser, which means the raw file a crawler grabs first is close to empty. A human's browser fills in the blanks instantly, while an automated reader sees a sealed drawer with far less inside than what's really there.
Per Huq, Bigham & Martelaro (Carnegie Mellon), LLMs can retrieve important UI elements from web pages reasonably well, but there is still substantial room for improvement, and web UI is harder for them to process than mobile UI because it is more complex and has more elements on each page.
Why Mobile-First Gaps Compound the Problem
Now, that finding matters because a legacy site is already asking an AI system to do more guesswork than it should. Pile mobile-first gaps on top and the burden gets heavier, not lighter.
Mobile-first indexing means the mobile version of a page is treated as the primary version for evaluation. An older site with a stripped-down or inconsistent mobile layout is handing the system its weakest rendering of the facts. The server-response issue established earlier applies here too: a page a crawler can't properly index never reaches the retrieval pool at all.
The Operational Sequence a Rebuild Actually Follows
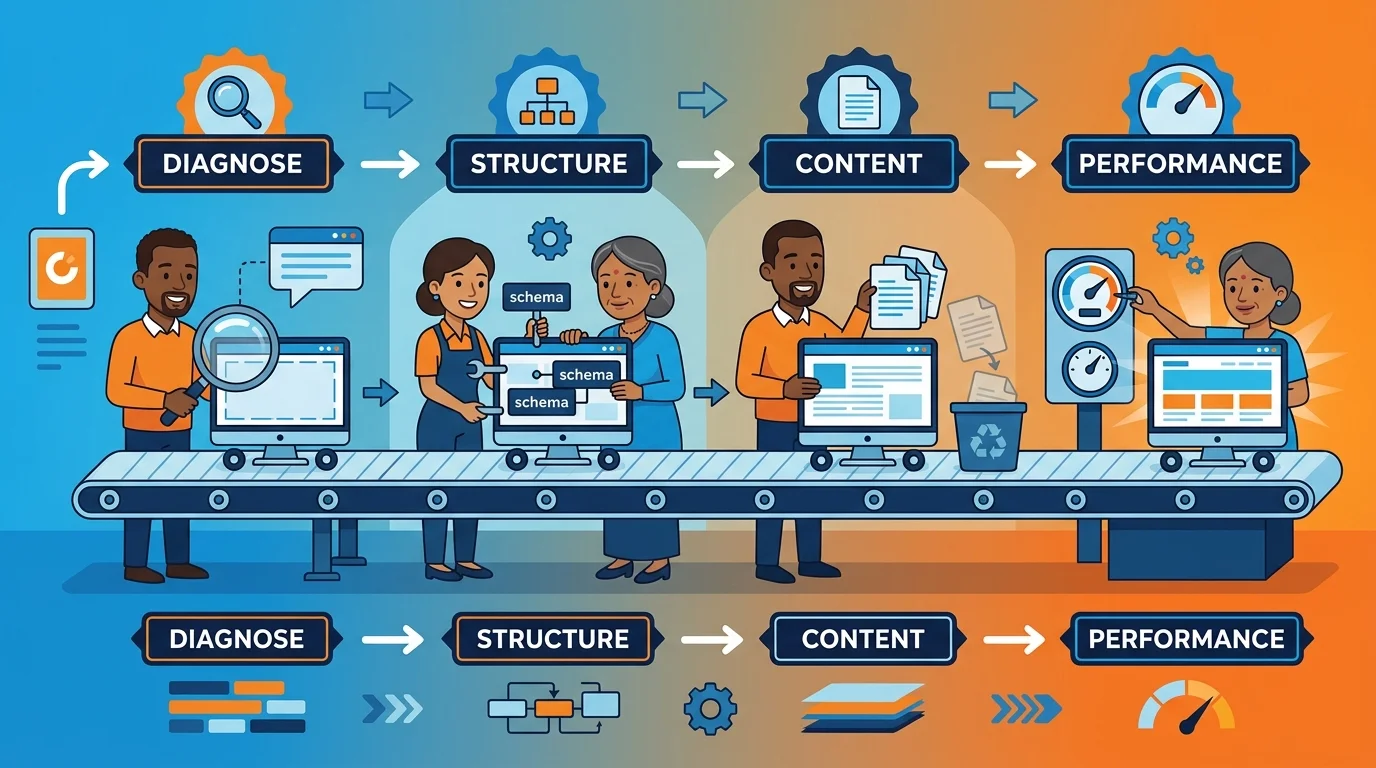
A rebuild doesn't start with a redesign. It starts with a diagnosis of what the current architecture is hiding from a crawler, and what the content layer is getting wrong on its own, separate from the code underneath.
| Rebuild Stage | Primary Fix Addressed | Dependency |
|---|---|---|
| Diagnostic Audit | Mapping every gap between what a crawler receives and what a human visitor sees, across server responses, markup, and rendering behavior | None — this stage must run first since every later fix depends on knowing where the gaps actually are |
| Structured Data Labeling | Giving a machine an accurate label for every fact on the page before any new content gets published | Depends on the diagnostic audit identifying where markup already contradicts visible text |
| Performance and Server Reliability Fixes | Making sure pages return a success response and load consistently enough to stay in the retrieval pool | Depends on structured data being in place, since a mislabeled page that also loads unreliably compounds both failures at once |
| Content Rebuild on Stable Architecture | Publishing content that an AI system can actually lift cleanly, now that the structure beneath it holds up | Depends on all three prior stages — content built before the architecture is fixed just repeats the sealed-cabinet problem |
Diagnosing the Architecture Before Writing a Line of Code
That diagnosis means auditing server responses, markup consistency, and rendering behavior before a single new page is written. It also means checking whether product and service pages follow the same structure across the site, since a diagnosis that stops at one template misses the unevenness the rest of the site carries.
So the first pass hunts down every spot where a crawler gets less than a human visitor sees. Client-side rendering gaps count, and so does any page returning something other than a success response.
Sequencing Structured Data, Content, and Performance Fixes
Once those gaps are mapped, structured data comes first, because it labels the facts a machine needs before any new content is published. Performance fixes follow immediately after. Content work comes last, built on a foundation that can finally be read.
Frequently Asked Questions
Once the technical case clicks, the questions get specific. These are the ones operators ask most after they see what a rebuild actually fixes.
Can't I just update my content and skip a full site rebuild for AI visibility?
No. Content sits on top of infrastructure, and infrastructure decides whether a crawler can reach that content at all. A new paragraph can't fix an inconsistent markup structure or a server response an AI system can't parse.
What is the single biggest technical issue on old sites that blocks AI crawlers?
Inconsistent or outdated markup is the most common blocker, since it leaves a crawler guessing which part of a page to trust. A close second is a server response that fails outright, because a page isn't indexed at all once that happens.
How long does it take for a new site to start getting cited in AI answers?
Let's keep it real: there's no fixed timeline, and any promise of one deserves a raised eyebrow. What matters is sequence. Structured data, then performance, then content on a foundation machines can read.
Why does structured data matter more now than it did for older search engines?
Older search engines matched keywords against pages and let a human decide what was true. AI systems lift facts directly, so the markup has to match the visible text.
How does mobile-first indexing affect a site's eligibility for AI-generated answers?
Mobile-first indexing treats the mobile version of a page as the primary version evaluated. An older site with a stripped-down mobile layout is handing the system its weakest rendering of the facts, which limits what gets surfaced.
The Bottom Line
A sealed filing cabinet isn't a broken one. The documents inside are accurate, the folders are labeled, and the facts all check out. But nothing crawling the building can open the drawers, so none of it counts.
That is the condition of a site that delays its rebuild. Delaying a necessary site rebuild in the age of AI search isn't just a technical issue. It's a strategic failure that actively hands the next generation of search to whichever competitor already built an archive AI systems can read and cite.
AI visibility was never about placing in traditional ranked results. It's about being understood and trusted enough by a machine to be cited as a source of truth, and that trust has to be built into the structure, not bolted onto the content. So the choice sitting in front of every outdated chiropractic site is the same one: stay a sealed cabinet, or become the open, labeled archive a machine can actually cite, starting with an AI Visibility Check. iTech Valet's first recommendation is a full rebuild: the site moves onto the iTech Valet Authority Platform, which is built for AI visibility, gets a design update, and is handled end to end by iTech Valet. A practice that must keep its current website can have it reworked instead, with the sales copy rewritten on what it already has. Every case is looked at on its own.